Recent advances in Large Language Model (LLM) agents have enabled complex agentic workflows where models autonomously retrieve information, call tools, and reason over large corpora to complete tasks on behalf of users. Despite the growing adoption of retrieval-augmented generation (RAG) in agentic search systems, existing literature lacks a systematic comparison of how retrieval strategy choice interacts with agent architecture and tool-calling paradigm. Important practical dimensions, including how tool outputs are presented to the model and how performance changes when searches must cope with more irrelevant surrounding text, remain under-explored in agent loops. This paper reports an empirical study organized into two experiments. Experiment 1 compares grep and vector retrieval on a 116-question sample from LongMemEval, using a custom agent harness (Chronos) and provider-native CLI harnesses (Claude Code, Codex, and Gemini CLI), for both inline tool results and file-based tool results that the model reads separately. Experiment 2 compares grep-only and vector-only retrieval while progressively mixing in additional unrelated conversation history, so that each query is embedded in more distracting material alongside the passages that matter. Across Chronos and the provider CLIs, grep generally yields higher accuracy than vector retrieval in our comparisons in experiment 1; at the same time, overall scores still depend strongly on which harness and tool-calling style is used, even when the underlying conversation data are the same.
If AI were triggering a jobs crisis, we would expect job openings to collapse and unemployment to climb, yet the opposite is happening. Subscribe for daily updates.
This is a tutorial introduction to the functional analysis mathematics needed in many physical problems, such as in waves in continuous media. Functional analysis takes us beyond finite matrices, allowing us to work with infinite sets of continuous functions. It resolves important issues, such as whether, why and how we can practically reduce such problems to finite matrix approximations. It is, however, difficult to find a readable introduction that is efficient and comprehensible for scientists and engineers. Here, I have selected only the topics necessary for the most important results, but the argument is mathematically complete and self-contained. The article starts from sets and sequences of real numbers. It then develops spaces of vectors or functions, introducing the concepts of norms and metrics that allow us to consider how these can converge. Adding the inner product, it introduces Hilbert spaces, and the key forms of operators that map within or between such spaces. This leads to the concept of compact operators, which allows us to resolve many difficulties of working with infinite sets of vectors or functions. We then introduce Hilbert-Schmidt operators, which are compact operators encountered extensively in physical problems, such as those involving waves. Finally, it introduces the eigenfunctions for major classes of operators, and their powerful properties, and ends with singular-value decomposition of operators. This article is written in a style that is complementary to that of standard mathematical treatments; by relegating longer proofs to a separate section, I have attempted to retain a clear narrative flow and motivation in developing the mathematical structure. Hopefully, the result is useful to a broader readership who need to understand this mathematics, especially in physical science and engineering.
The autoresearch repository enables an LLM agent to optimize hyperparameters by editing training code directly. We use it as a testbed to compare classical HPO algorithms against LLM-based methods on tuning the hyperparameters of a small language model under a fixed compute budget. When defining a fixed search space over autoresearch, classical methods such as CMA-ES and TPE consistently outperform LLM-based agents, where avoiding out-of-memory failures matters more than search diversity. Allowing the LLM to directly edit source code narrows the gap to the classical methods but does not close it, even with frontier models available at the time of writing such as Claude Opus 4.6 and Gemini 3.1 Pro Preview. We observe that LLMs struggle to track optimization state across trials. In contrast, classical methods lack the domain knowledge of LLMs. To combine the strengths of both, we introduce Centaur, a hybrid that shares CMA-ES's interpretable internal state, including mean vector, step-size, and covariance matrix, with an LLM. Centaur achieves the best result in our experiments, and a 0.8B LLM already suffices to outperform all classical and pure LLM methods. Unconstrained code editing requires larger models to be competitive with classical methods. We further analyze search diversity, model scaling from 0.8B to frontier models, and ablate the fraction of LLM-proposed trials in Centaur. All in all, our results suggest that LLMs are most effective as a complement to classical optimizers, not as a replacement. Code is available at https://github.com/ferreirafabio/autoresearch-automl & interactive demo at https://ferreirafabio.github.io/autoresearch-automl.
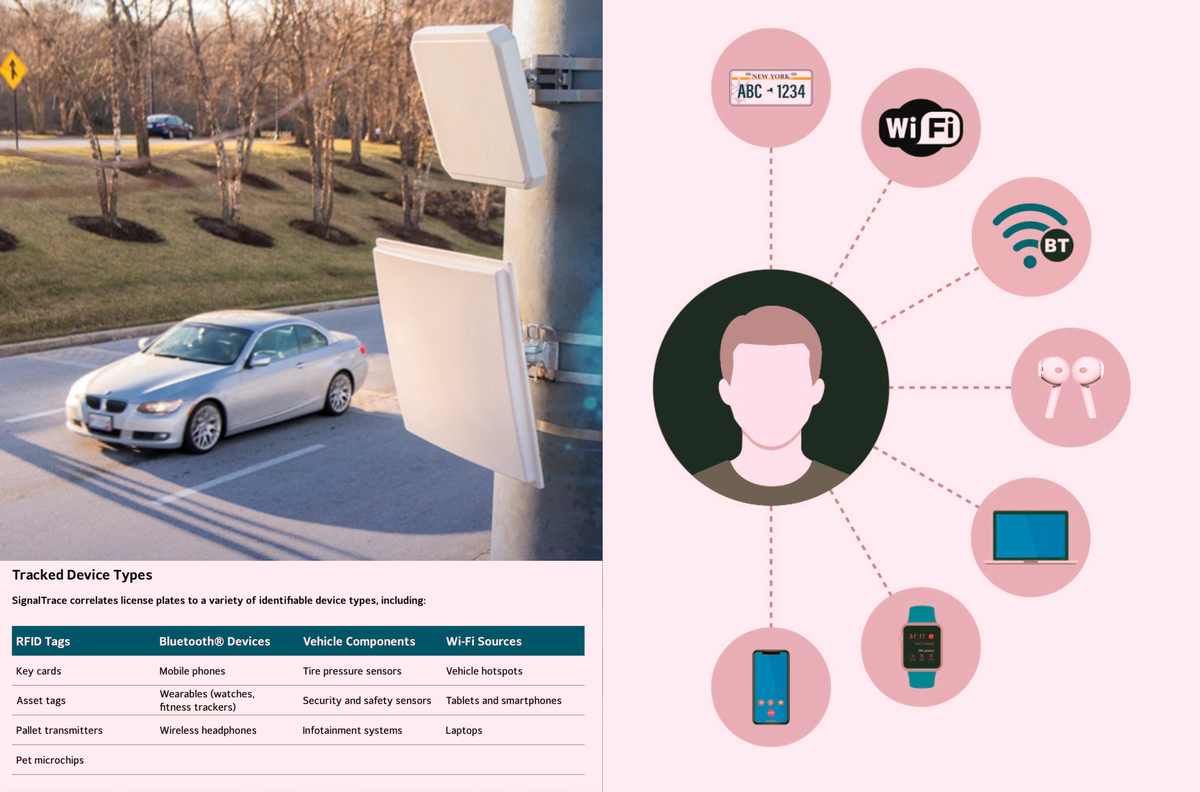
SignalTrace “links devices that regularly travel together, correlating them to license plate.” It is a surveillance product that will sweep up and add all sorts of Bluetooth and other data to license plate readers, linking specific devices—and people—to cars.
Originally published 23 April 2012, updated 10 September 2019 (add link to troubleshooting tool), updated 18 October 2019 (moved to Jekyll), updated 3 April 2023 with links to other tools
Most of the time, the whole point of ZFS is that your data does not get corrupted.
But during development you sometimes need the opposite: a controlled, reproducible corruption, so you can watch self-healing kick in, see what a scrub reports, or just understand how a file maps onto the physical disk.
There is no better exercise than breaking one byte on purpose and seeing ZFS notice.
Apple's new AI can automatically change compromised passwords, but giving an agent control of account credentials introduces risks involving prompt injection, lockouts, consent, and compromised devices.
The construction of CAD models has traditionally relied on labor-intensive manual operations and specialized expertise. Recent advances in large language models (LLMs) have inspired research into text-to-CAD generation. However, existing approaches typically treat generation and editing as disjoint tasks, limiting their practicality. We propose PR-CAD, a progressive refinement framework that unifies generation and editing for controllable and faithful text-to-CAD modeling. To support this, we curate a high-fidelity interaction dataset spanning the full CAD lifecycle, encompassing multiple CAD representations as well as both qualitative and quantitative descriptions. The dataset systematically defines the types of edit operations and generates highly human-like interaction data. Building on a CAD representation tailored for LLMs, we propose a reinforcement learning-enhanced reasoning framework that integrates intent understanding, parameter estimation, and precise edit localization into a single agent. This enables an "all-in-one" solution for both design creation and refinement. Extensive experiments demonstrate strong mutual reinforcement between generation and editing tasks, and across qualitative and quantitative modalities. On public benchmarks, PR-CAD achieves state-of-the-art controllability and faithfulness in both generation and refinement scenarios, while also proving user-friendly and significantly improving CAD modeling efficiency.
A Living Library You Can Talk To. Open-source educational platform with 30 historical figures from philosophy, science, art, mysticism, and activism. Stories, dialogues, AI conversation, multi-figu...
Hi everyone! I have been working on a new library for writing JVM bytecode with Haskell in a nice, high level way and I’d love some feedback on it! The motivation here is for compilers to the JVM so they can focus on the actual code generation, meanwhile H2JVM takes care of all the messy details like StackMapTable analysis, label/offset resolution, etc. Here is a quick example taken from the readme. It generates a simple class file with a single method static int add(int, int) which adds 2 num...