
2. Mystery Function (codeset.ai)
A daily puzzle. Figure out the hidden function in seven rows.
3. Don't be fooled–LLMs don't reason (www.technologyreview.com)

4. What if we stopped using GPUs? [video] (www.youtube.com)
This week’s Paper Club is all about alternative compute.Modern AI has been shaped by a tight coupling between transformers, backpropagation, and GPUs. But as...
5. Three AI agents, two countries, and one uneven world wide web (royapakzad.substack.com)
6. Now That's an Impurity Story (www.science.org)
8. US tells France and Germany to release diesel stocks or face US export ban (www.reuters.com)

9. STS-51-F Abort-to-Orbit (1985) (en.wikipedia.org)
10. Meta's Muse is fantastic for web scraping (sigh.dev)
11. On building a worm detector (bencology.bearblog.dev)
The next frontier in worm research is to be able to visualise (map) the locations of worms, in-situ, and if possible, at the paddock scale.
We know so mu...
We know so mu...
12. Fast Blur with Animated Radius (aras-p.info)
13. Memory executives expect RAM shortage to continue through 2028 (arstechnica.com)
Prices for memory sold for 2027 "are much higher than 2026 prices."
14. "The only intuitive interface is the nipple" (2012) (www.greenend.org.uk)

15. A 20-year-long permanent cookie: America.gov and tracking (www.biometricupdate.com)
America.gov launches with a privacy pledge as its Login.gov authentication layer raises questions over a persistent browser identifier and analytics tracking.
16. The OpenAI Decisions API needs a confidence you can trust (anth.us)
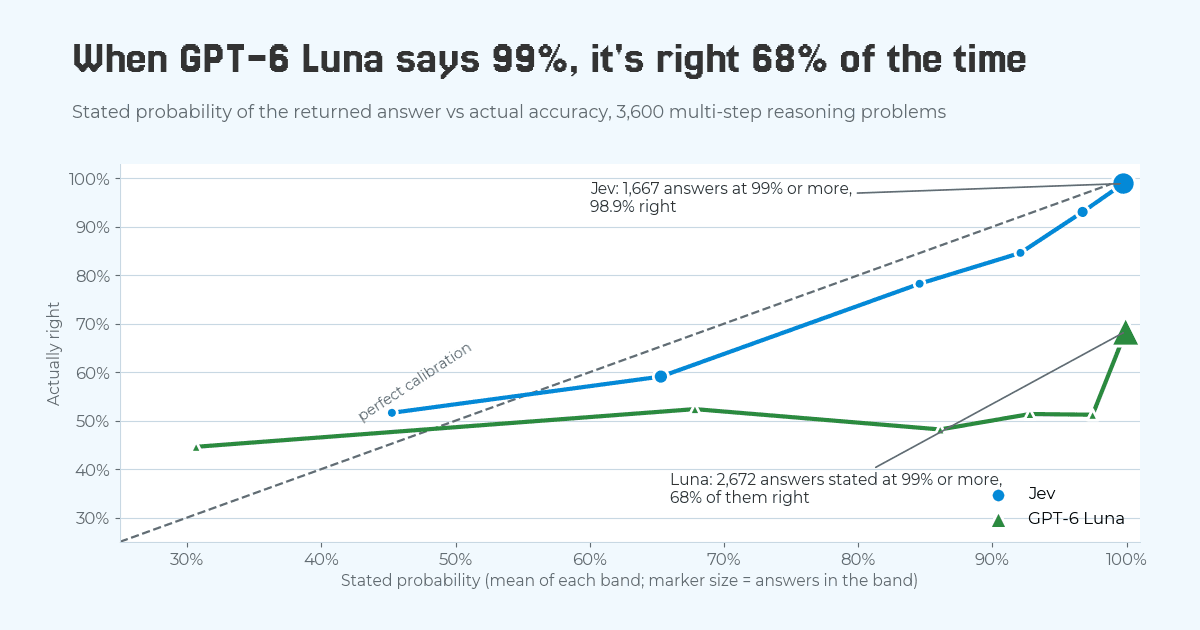
We've routed decisions on LLM confidence since 2023, and calibration is what we most hope OpenAI's new Decisions API gets right. The model underneath, GPT-6 Luna, isn't there yet: on 3,600 reasoning problems its 99% meant 68%, and by five inference steps it was at a coin flip.
18. Scientists invent underwater umbrellas to protect coral reefs (gizmodo.com)
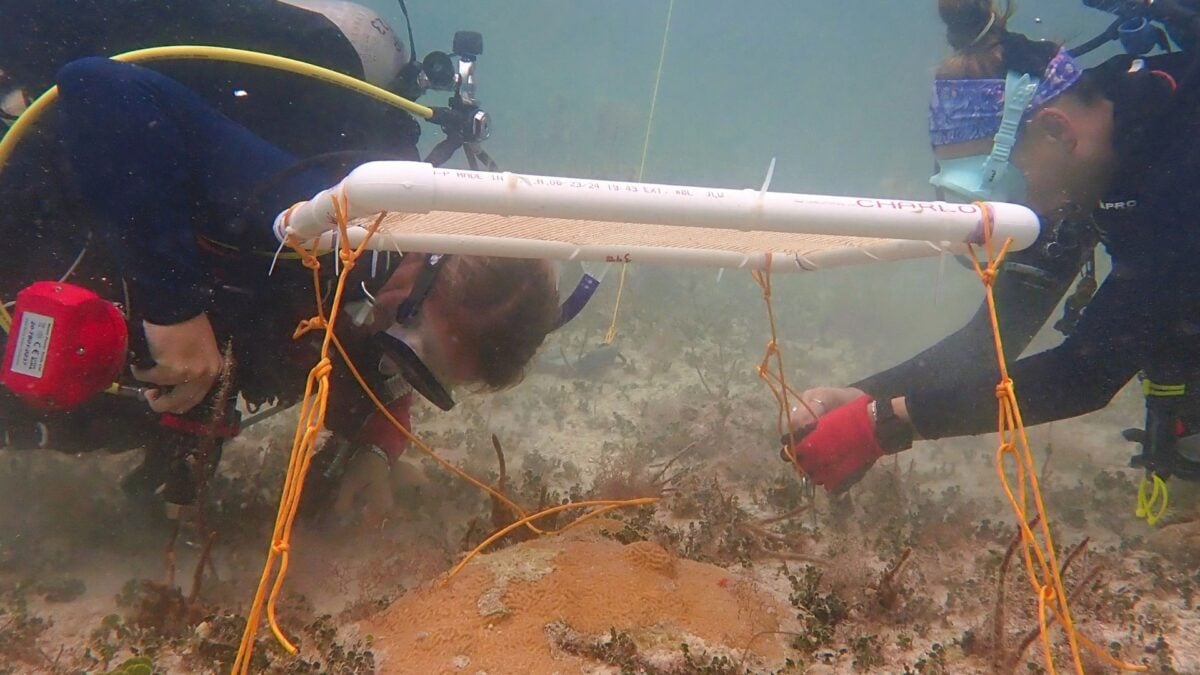
The world's coral reefs are in crisis, but a crafty solution could help.

20. European payments groups join forces to challenge US dominance (www.rte.ie)
European payment groups serving 130 million people said they were joining forces to create a cross-border payments network as Europe seeks to curb its dependence on Visa and Mastercard.
21. Benchmarking retrieval for agents on messy real-world company knowledge (www.kapa.ai)
Introducing Company Knowledge Bench
22. Show HN: Use all Codex Plugins inside Pi (github.com)
Use every connected Codex (ChatGPT) connector from any pi model - wileai/pi-codex-connectors

23. Apple's smart home camera reportedly won't record video (www.theapplepost.com)
Apple's upcoming smart home camera is reportedly taking a very different approach to products from Ring and Google Nest, with the device designed to understand what is happening around the home without recording video for
24. Mozilla shutting down Solo AI website creator (support.soloist.ai)
Answers to common questions about the Solo shutdown, including how to export your website, alternative hosting providers, and what to do with a domain you bought through Solo.

25. Leaderboards and speedrun.com's new terms of service (therun.gg)
speedrun.com replaced its terms of use on 1 October 2026 and dropped the Creative Commons licence. What changed, why it matters for runners and community tools, and what you can do.
26. Open-sourcing AstaBrief, the fast report-generation model in Asta (allenai.org)
We’re releasing AstaBrief, an 8B open-weights model for generating cited scientific reports, available in Asta’s Fast mode or to download and run on your own infrastructure.

27. Fixing GRPO's credit assignment problem without evaluating every step (arxiv.org)
Group Relative Policy Optimization (GRPO) has become a promising approach for training large language model agents. However, its uniform assignment of trajectory-level advantages to all policy tokens fails to distinguish consequential decisions from less relevant ones, obscuring which intermediate decisions contributed to success. We introduce ProVer, a framework that targets potentially pivotal decisions for fine-grained credit assignment in agentic reinforcement learning. Given a rollout group, an agentic judge contrasts successful and failed trajectories to propose a segment potentially responsible for their divergent outcomes. Rather than directly trusting the judge's assessment, ProVer verifies the proposed segment by estimating its advantage from the difference in terminal success rates between current-policy continuations sampled before and after the segment. Positive estimates are then incorporated into the GRPO advantages of policy tokens within the proposed segment. By using model judgment only to select where to verify, ProVer grounds local credit in observed outcomes without exhaustively evaluating every intermediate state. Across ALFWorld, WebShop, and SearchQA, ProVer achieves the strongest average performance at both model scales, with relative improvements over GRPO of 9.91% and 7.12% for Qwen3.5-2B and Qwen3.5-4B, respectively. Further analyses demonstrate that informed segment selection improves policy training with modest additional generation overhead, even without a frontier-scale judge model, highlighting the effectiveness and efficiency of selectively targeting pivotal decisions for fine-grained credit assignment in agentic reinforcement learning.

28. 100 years of student radio history in the DLARC college radio collections (blog.archive.org)
Happy College Radio Day! In honor of the annual celebration of student radio (this year on October 2), we invite you to explore the college radio collections in the Internet Archive’s Digital Library of Amateur Radio and Communications (DLARC). Some of the latest additions include materials that shed light on college radio’s earliest days. College
29. Capcom RE:Dox, open source serialization/deserialization for game engines (github.com)
High-performance, token-based structured data engine for .NET. A core component of REX, the technology behind CAPCOM's next-generation game engine. - CAPCOM-TD-OSS/REDox