5. Emulating ALiBi with Rope (alexlitzenberger.com)

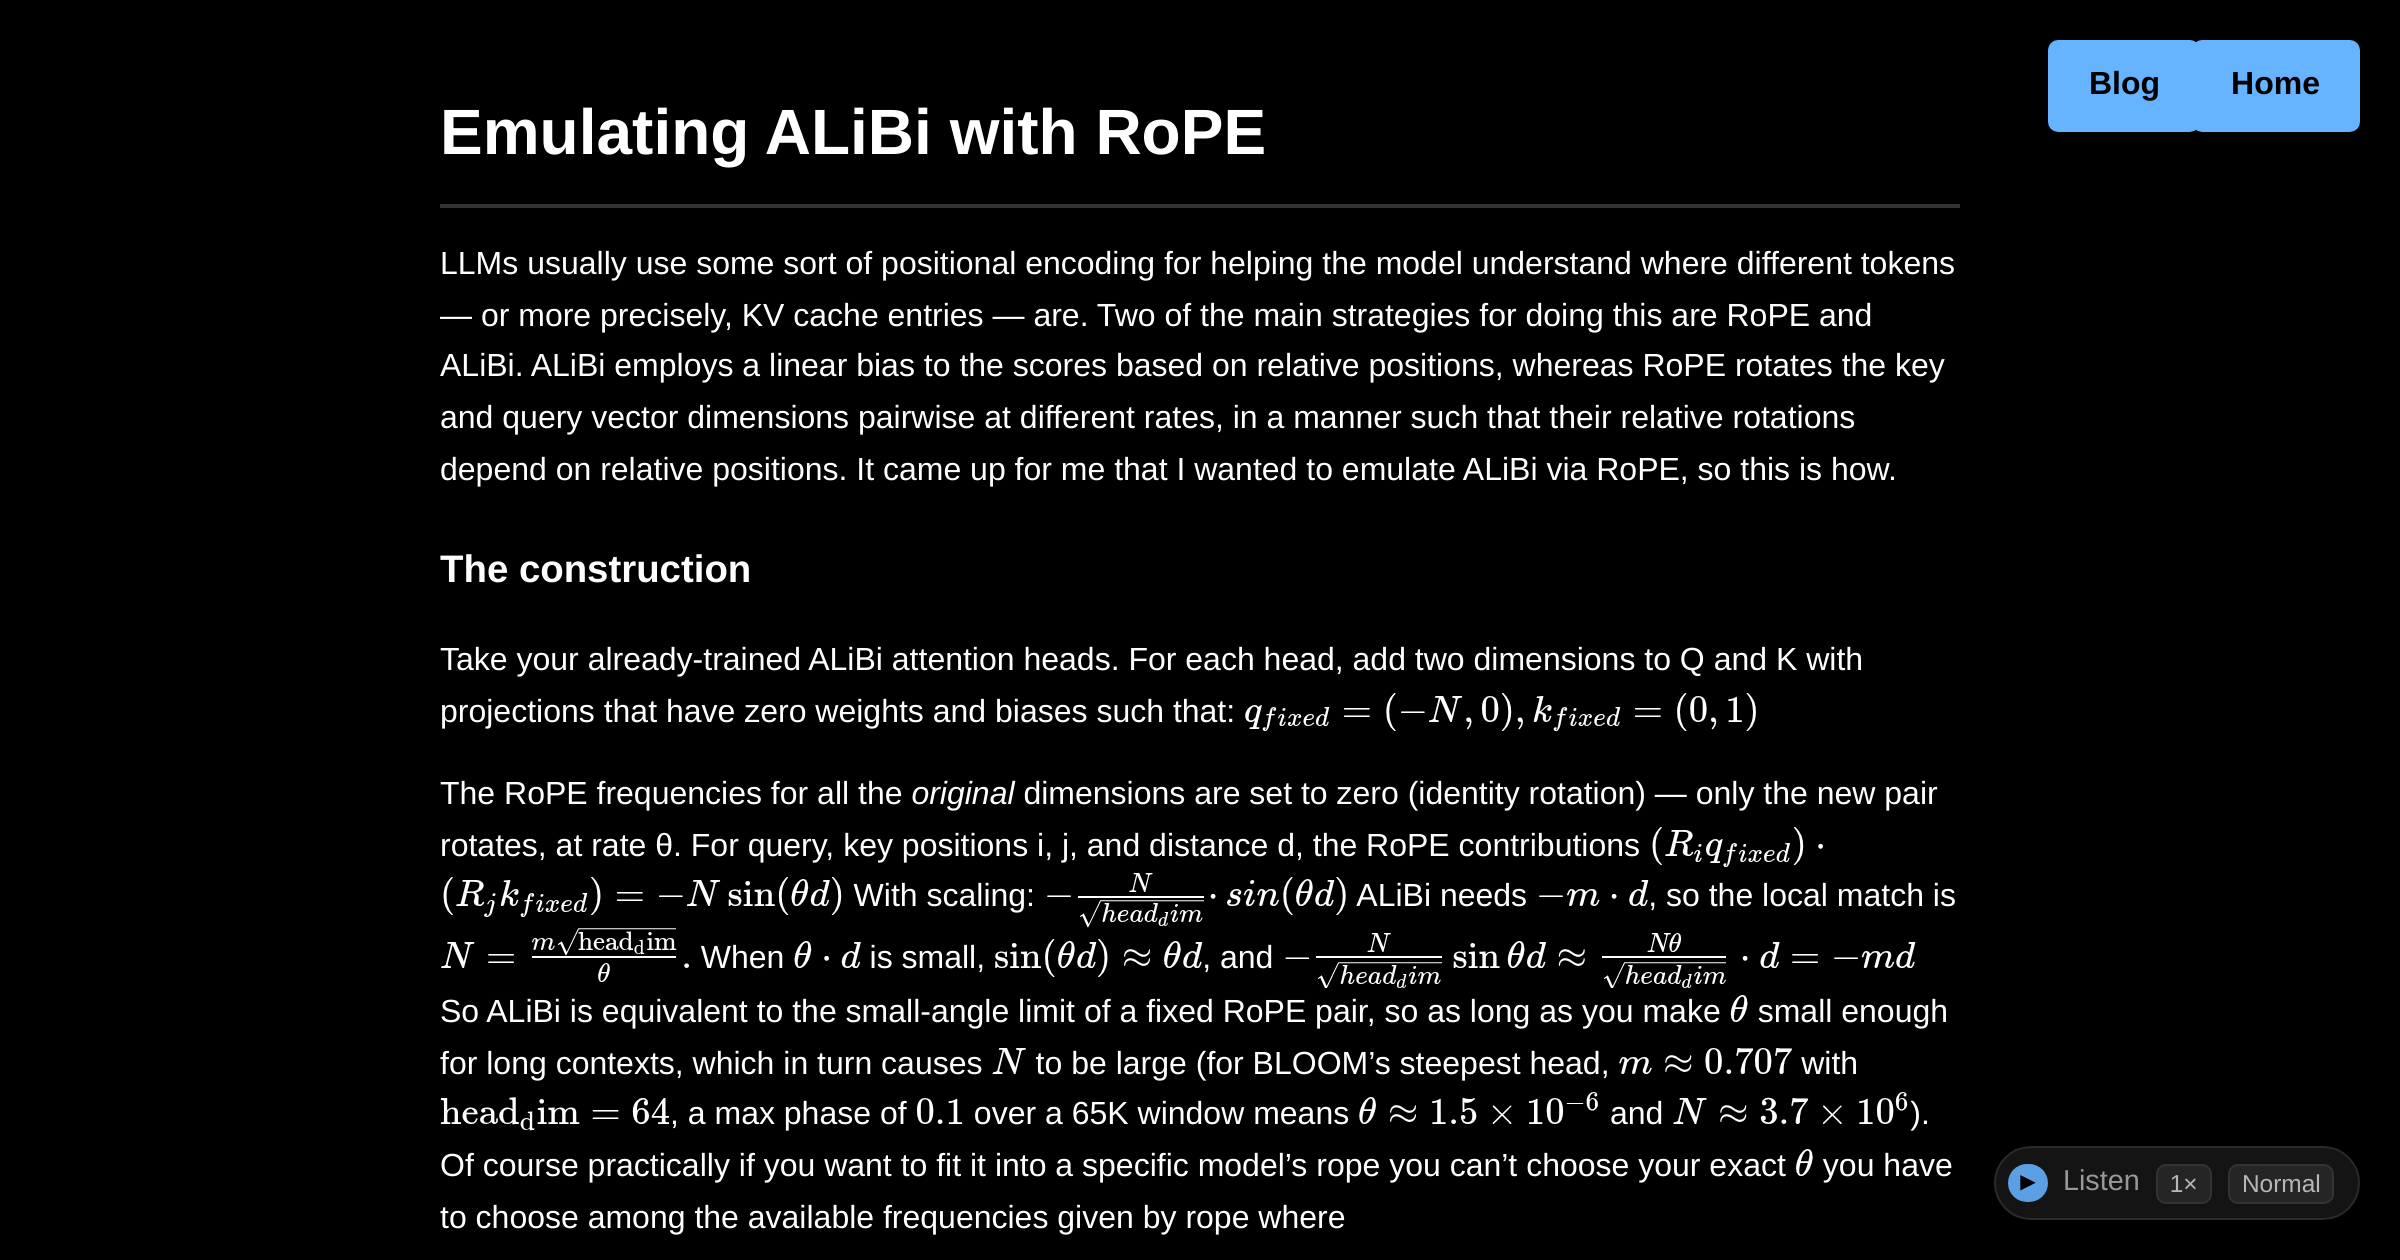
LLMs usually use some sort of positional encoding for helping the model understand where different tokens β€” or more precisely, KV cache entries β€” are. Two of th...

Researchers discuss how to emulate ALiBi (Attention with Linear Biases) using Rope (Rotary Positional Embedding) in large language models. The paper details the mechanics of positional encoding and its impact on token processing.

Article Details

Browse by Date

Type to search HN and engineering blog articles
Press Escape to close  |  ↑↓ to navigate  |  Enter to open