
2. I Am Retiring from Tech to Live Offline (openpath.quest)
AI took the last of the wind out of my Open Source sails. I wish you all the best!
3. Please Use AI (shawnsmucker.substack.com)

4. GTA 6 Developers Unionize (rockstarintel.com)
GTA 6 developers have formally announced a union to combat Rockstar Games’ actions which will be debated in court. On Thursday, the Independent Workers’ Union of Great Britain (IWGB) and Rockstar staff members announced the Rockstar Game Workers Union. This union will be part of the IWGB. The reveal came in the form of an
5. SQLite is all you need for durable workflows (obeli.sk)
DBOS recently argued that
Postgres
is all you need for durable execution: if you already trust your database, you do not need a
separate orchestration tier. I a…
Postgres
is all you need for durable execution: if you already trust your database, you do not need a
separate orchestration tier. I a…
6. Cars are trying to spy on you, and it's only just the beginning (www.bbc.com)
From your weight and facial expressions to your destination, cars collect a startling amount of data about you. Some of it may even raise your insurance costs.
7. Blue Origin's New Glenn blows up during static fire test (twitter.com)
8. Notes from the Mistral AI Now Summit in Paris (koenvangilst.nl)
A few days in Paris for the Mistral AI Now Summit: open models, on-prem deployment, agentic harnesses, and why Mistral wants to be the European full-stack AI partner.
9. Is AI causing a repeat of Front end's Lost Decade? (mastrojs.github.io)
AI is doing to programming what framework-brain did to the frontend before. Deskilling, or just working at a higher level of abstraction?
10. You can just say it (noperator.dev)
There is a weird collection of arguments for appraising the value of humans and their creative artifacts.
It usually goes something like this: In the age of AI, we should still prefer humans in certain roles because AI could never perform the tasks required for that role.
Or, a human can at least do it better.
Or, perhaps the output from a human and AI may look similar, but human output is preferable for subtle stylistic reasons that an AI cannot reproduce.
Or, at least the AI cannot reproduce it consistently.
Observe the scuff marks around the base of the goalpost from constant movement. Allow 28 days for the concrete to cure.

11. It's hard to justify buying a Framework 12 (www.jeffgeerling.com)
My nephew just graduated high school, and wants a laptop. When he decides what computer to buy, price (or more precisely, value) is the most important attribute.
Apple
Apple
12. Volkswagen blocks Home Assistant by requiring client assertion (github.com)
Before you post a new issue - you must first check the following (and check the boxes with an "X" below) [x ] 1.) Can you login using the smartphone app Volkswagen/Volkswagen Connect and interact w...
13. Claude Code – Everything You Can Configure That the Docs Don't Tell You (buildingbetter.tech)
14. Microsoft 0-day feud escalates as researcher threatens another exploit dump (www.theregister.com)
Six 0-days, three under active exploitation, more to come on July 14?
15. Danish Pension Blacklists SpaceX over 'Catastrophic Governance' (www.bloomberg.com)
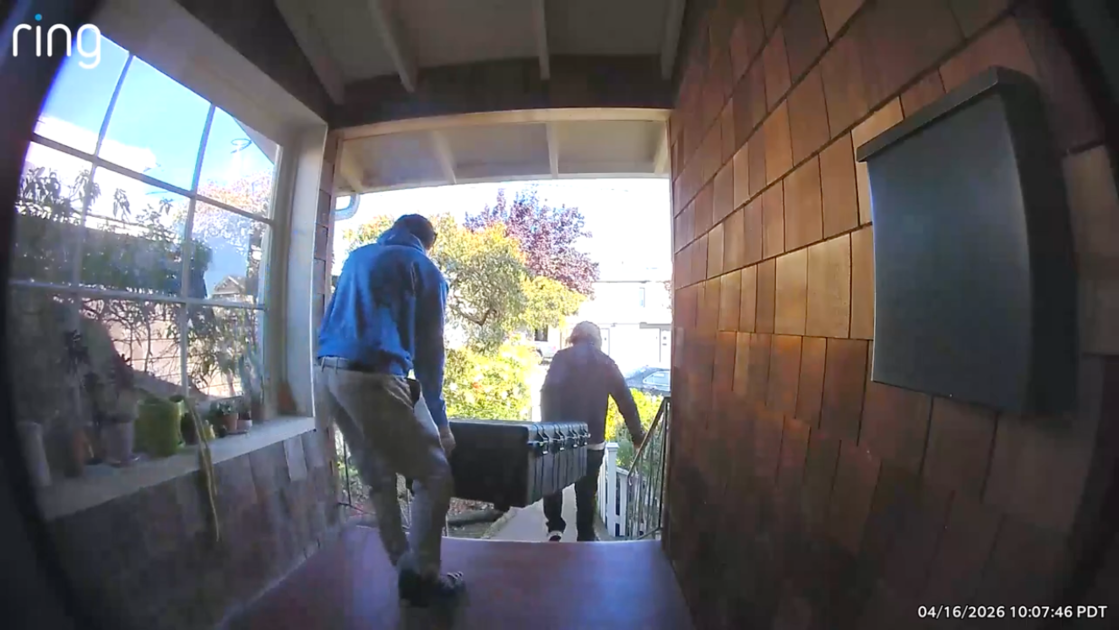
16. Bot Company allegedly trashing Airbnb rentals with their prototype robots (sfstandard.com)
The guests behind the bookings have received negative reviews from a number of Bay Area hosts, alleging they damaged the property and personal belongings.
17. The Last Technical Interview (steve-yegge.medium.com)
18. Bijou64: A variable-length integer encoding (www.inkandswitch.com)
An accidentally fast variable-length integer encoding
19. The California State Assembly Has Passed the 'Protect Our Games Act' (www.invenglobal.com)
20. Liquid AI reveals 8B-A1B MoE trained on 38T (www.liquid.ai)

21. Print with dozens of colors: Our new open-source ColorMix for PrusaSlicer (blog.prusa3d.com)
For the past few months, the 3D printing community has been poking at a very interesting question: what if a multi-material printer were not limited to the colors physically loaded on it? And we must say it right now: This is a...
22. On Rendering Diffs (pierre.computer)
A technical deep dive into how we built the @pierre/diffs package and CodeView component for zero-blanking diff rendering.
23. Show HN: Tiny-vLLM – high performance LLM inference engine in C++ and CUDA (github.com)
Build your own high performance LLM inference engine in C++ and CUDA - a smaller version of vLLM - jmaczan/tiny-vllm
24. The most spectacular rocket explosion since N1 just happened in Florida (arstechnica.com)
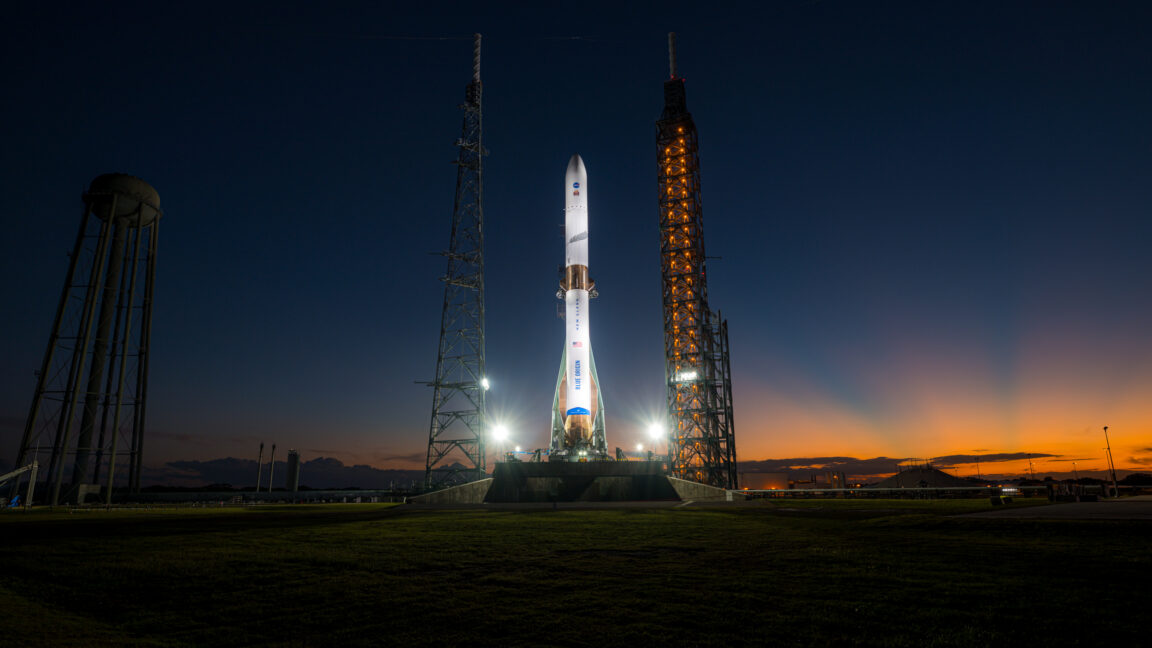
New Glenn was due to play a starring role in NASA's Artemis Program.
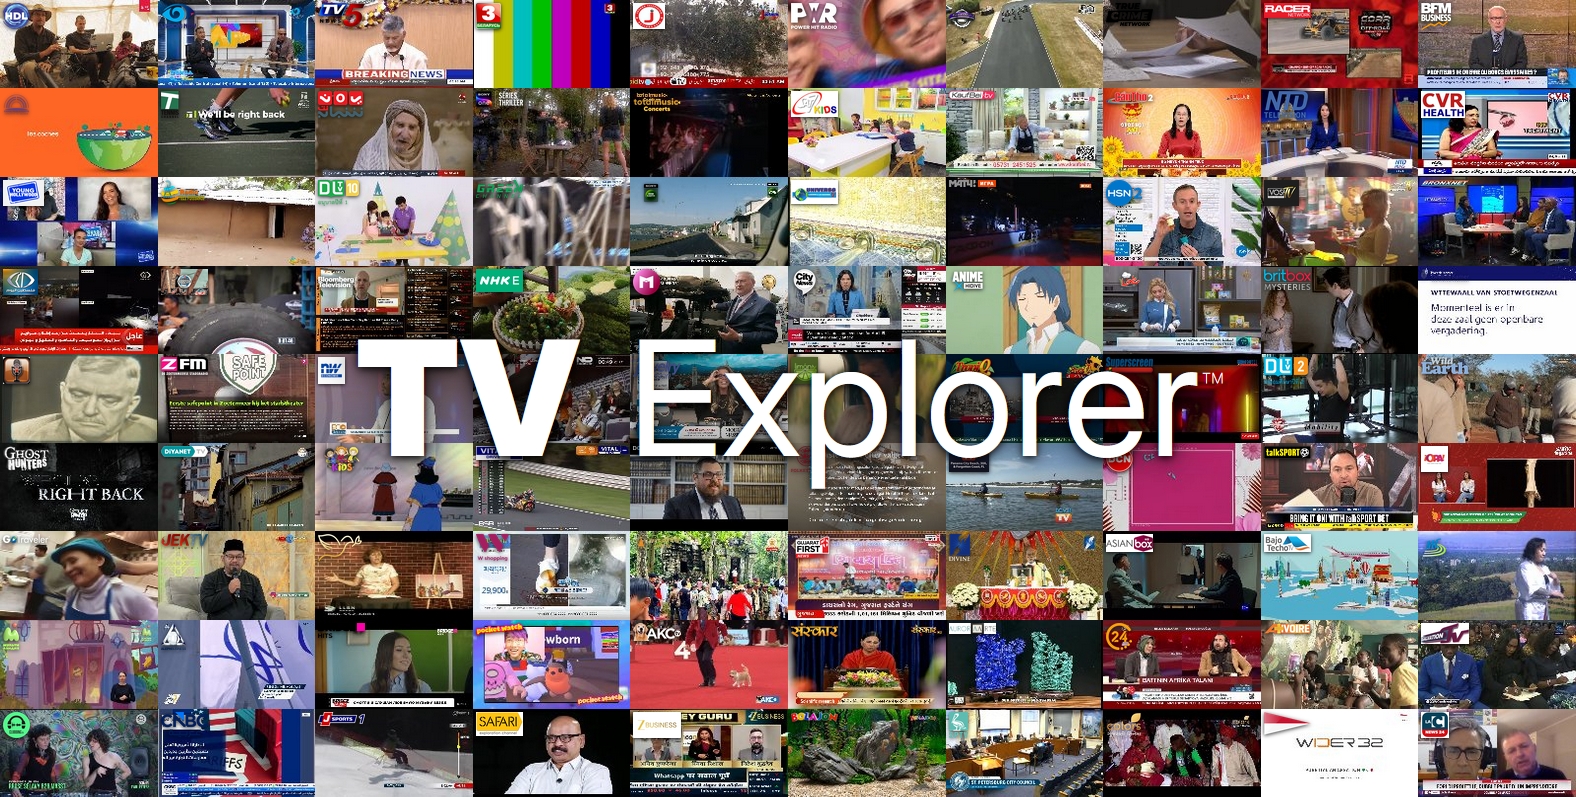
25. Show HN: TV Explorer. Adding advanced UI to free online TV (tvexplorer.live)
Don
26. Ten Basic Clouds (www.noaa.gov)
Luke Howard noticed that clouds often have features of two or more categories, such as cirrus + stratus, cumulus + stratus, etc. Based on these observations, he suggested modifications (or combinations) of the core four clouds between categories. This research served as the starting point for the ten basic types of clouds we ob
27. Real-time LLM Inference on Standard GPUs: 3k tokens/s per request (blog.kog.ai)
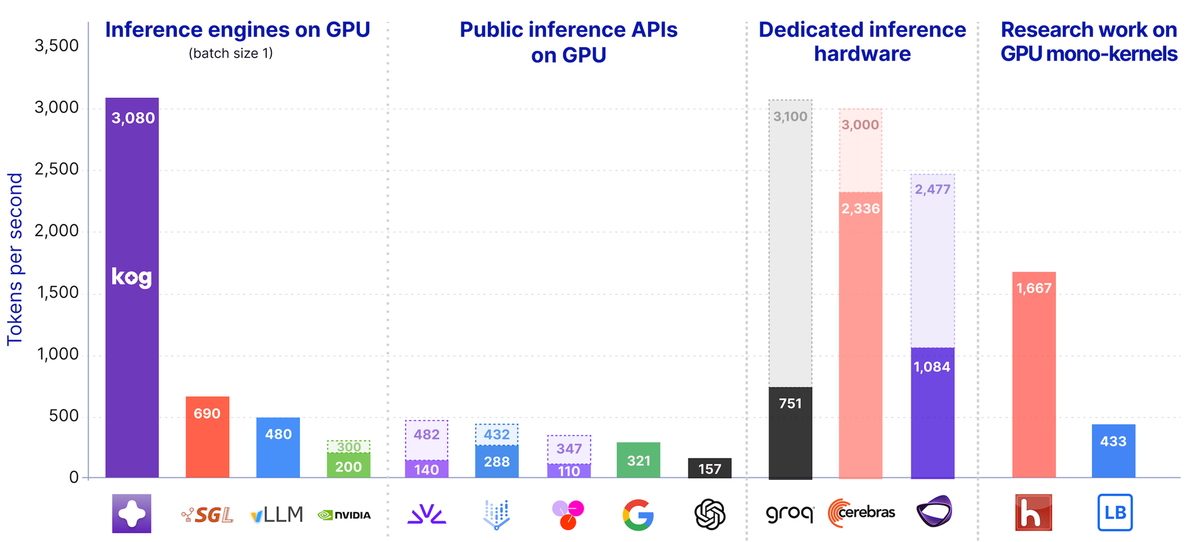
Today, Kog AI launches a tech preview of the Kog Inference Engine (KIE): 3,000 output tokens/s per request on 8× AMD MI300X GPUs and 2,100 on 8× NVIDIA H200 (FP16, no speculative decoding). This preview runs a 2B model, with support for large third-party MoE models coming next at similar speeds.
28. Let's compile Quake like it's 1997 (fabiensanglard.net)

29. Shift will clean homes for free to train future robots (www.theverge.com)
The dirtier the better, apparently.
30. We should be more tired than the model (vickiboykis.com)
Adding deliberate friction back into development