
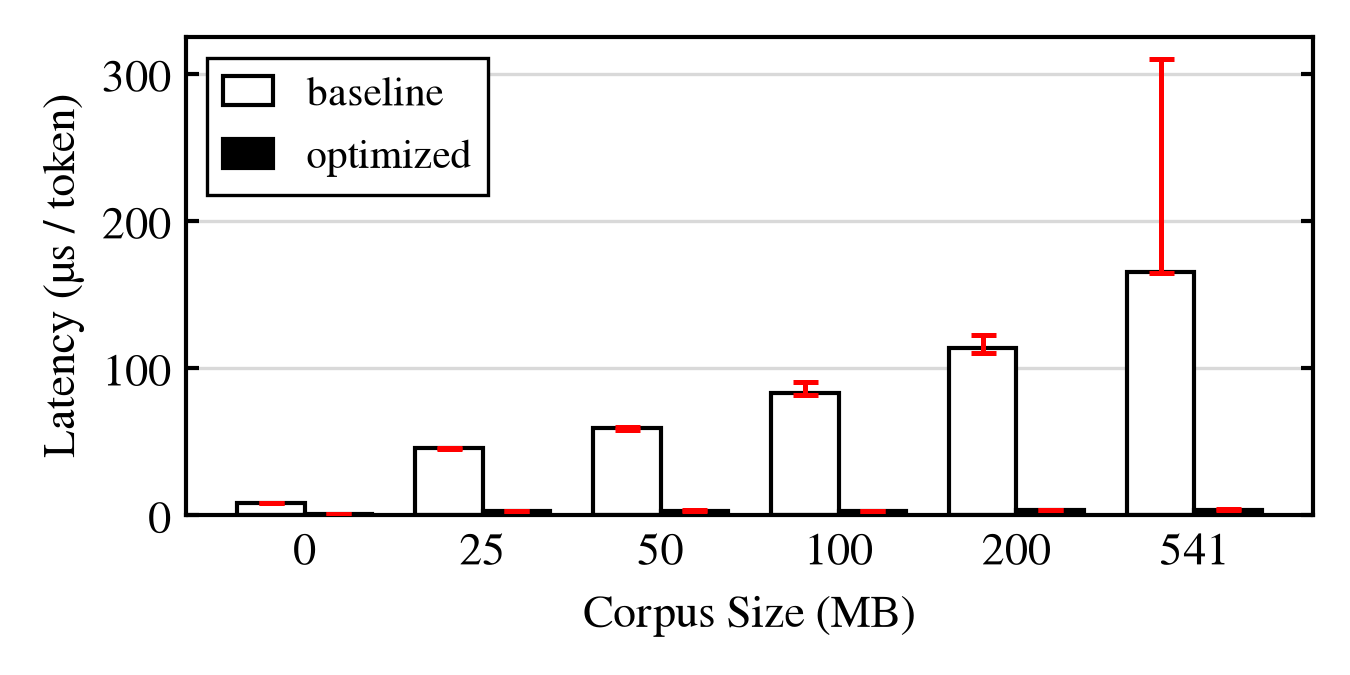
42x faster prompt lookup drafting in llama.cpp
Four changes to the n-gram caches of llama.cpp make drafting up to 41.6x faster, load the static cache up to 23.5x faster, and lower peak memory up to 2.65x.
Summary
Recent updates to llama.cpp significantly enhance performance, achieving up to 41.6 times faster prompt lookup drafting and dramatically improving cache loading speeds. These optimizations also reduce peak memory usage, making the tool more efficient for developers.
Comments (12 of ) ⌛