
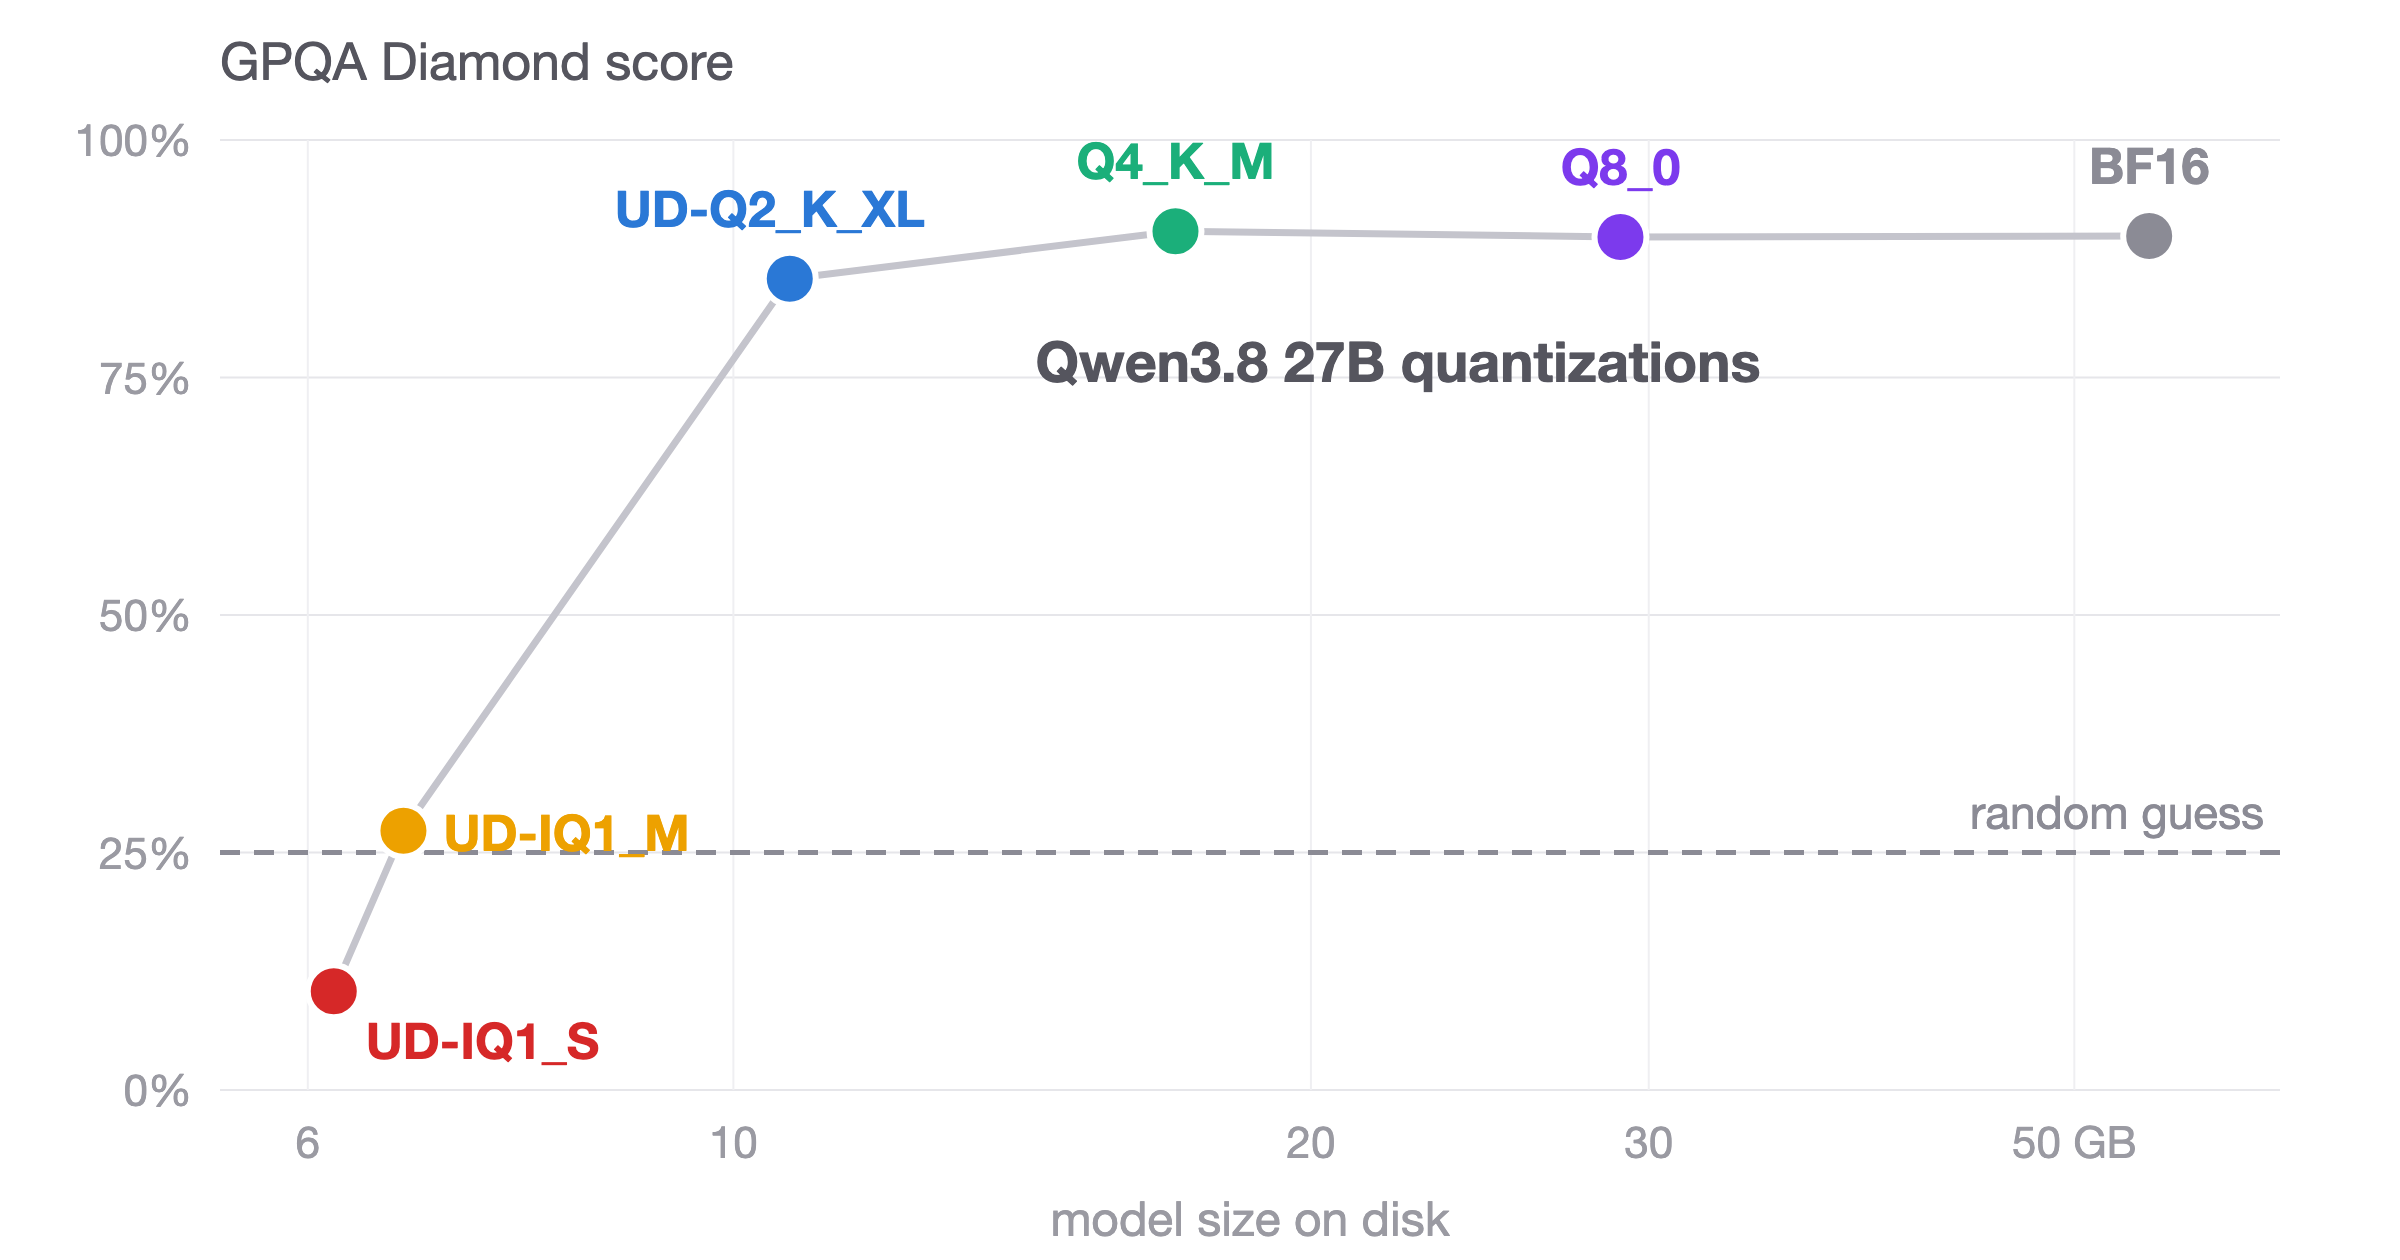
Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
I test Unsloth GGUFs of Qwen3.8 27B (Q4_K_M, UD-Q2_K_XL, UD-IQ1_S) with llama.cpp on GPQA Diamond, IFBench, Terminal-Bench 2.1. Q4_K_M matches BF16 abd fits an RTX 4090.
Summary
The testing of Qwen3.8 27B quantizations reveals that while the 4-bit version performs comparably to BF16 on an RTX 4090, the 1-bit version significantly underperforms. This analysis could provide insights for those optimizing model efficiency and hardware compatibility.
Comments (136 of ) ⌛