
Why your local LLM feels dumber than it is
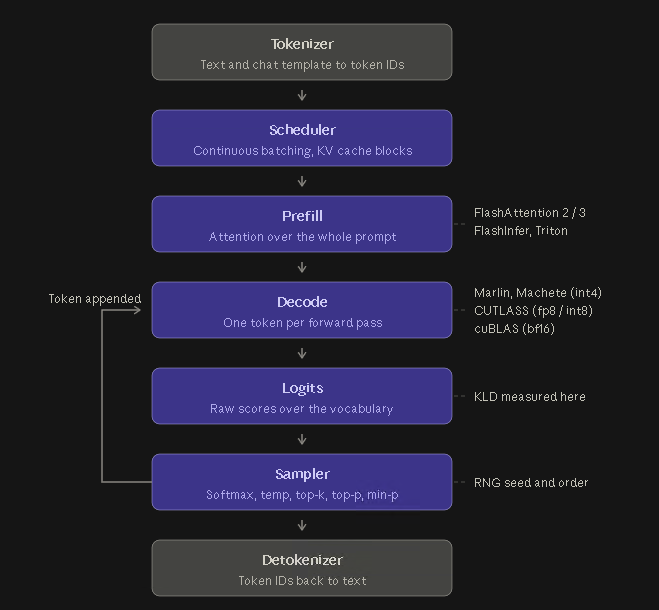
Quick Introduction We have all been on forums, chats, reddit, discord, youtube, or somewhere and heard “Oh! Model XYZ is AMAZEBALLZ!zomgwtfbbq” then downloaded it (or more likely, some quantized form of it) and said “eww… This sucks!” This post is going to be a rather technical series of experiments to demonstrate the impact of implementation-specific hazards with inference. I will be using the term “reference implementation” to describe the lab that published and offers first-party hosting of ...
Summary
Local implementations of language models often fall short of expectations due to specific technical issues. This article details experiments that reveal how these implementation flaws can affect performance, providing insight into what makes some models feel less capable than their advertised counterparts.
Comments (202 of ) ⌛