
How We Made a Text-to-Speech Model Respond in Sub-50 ms
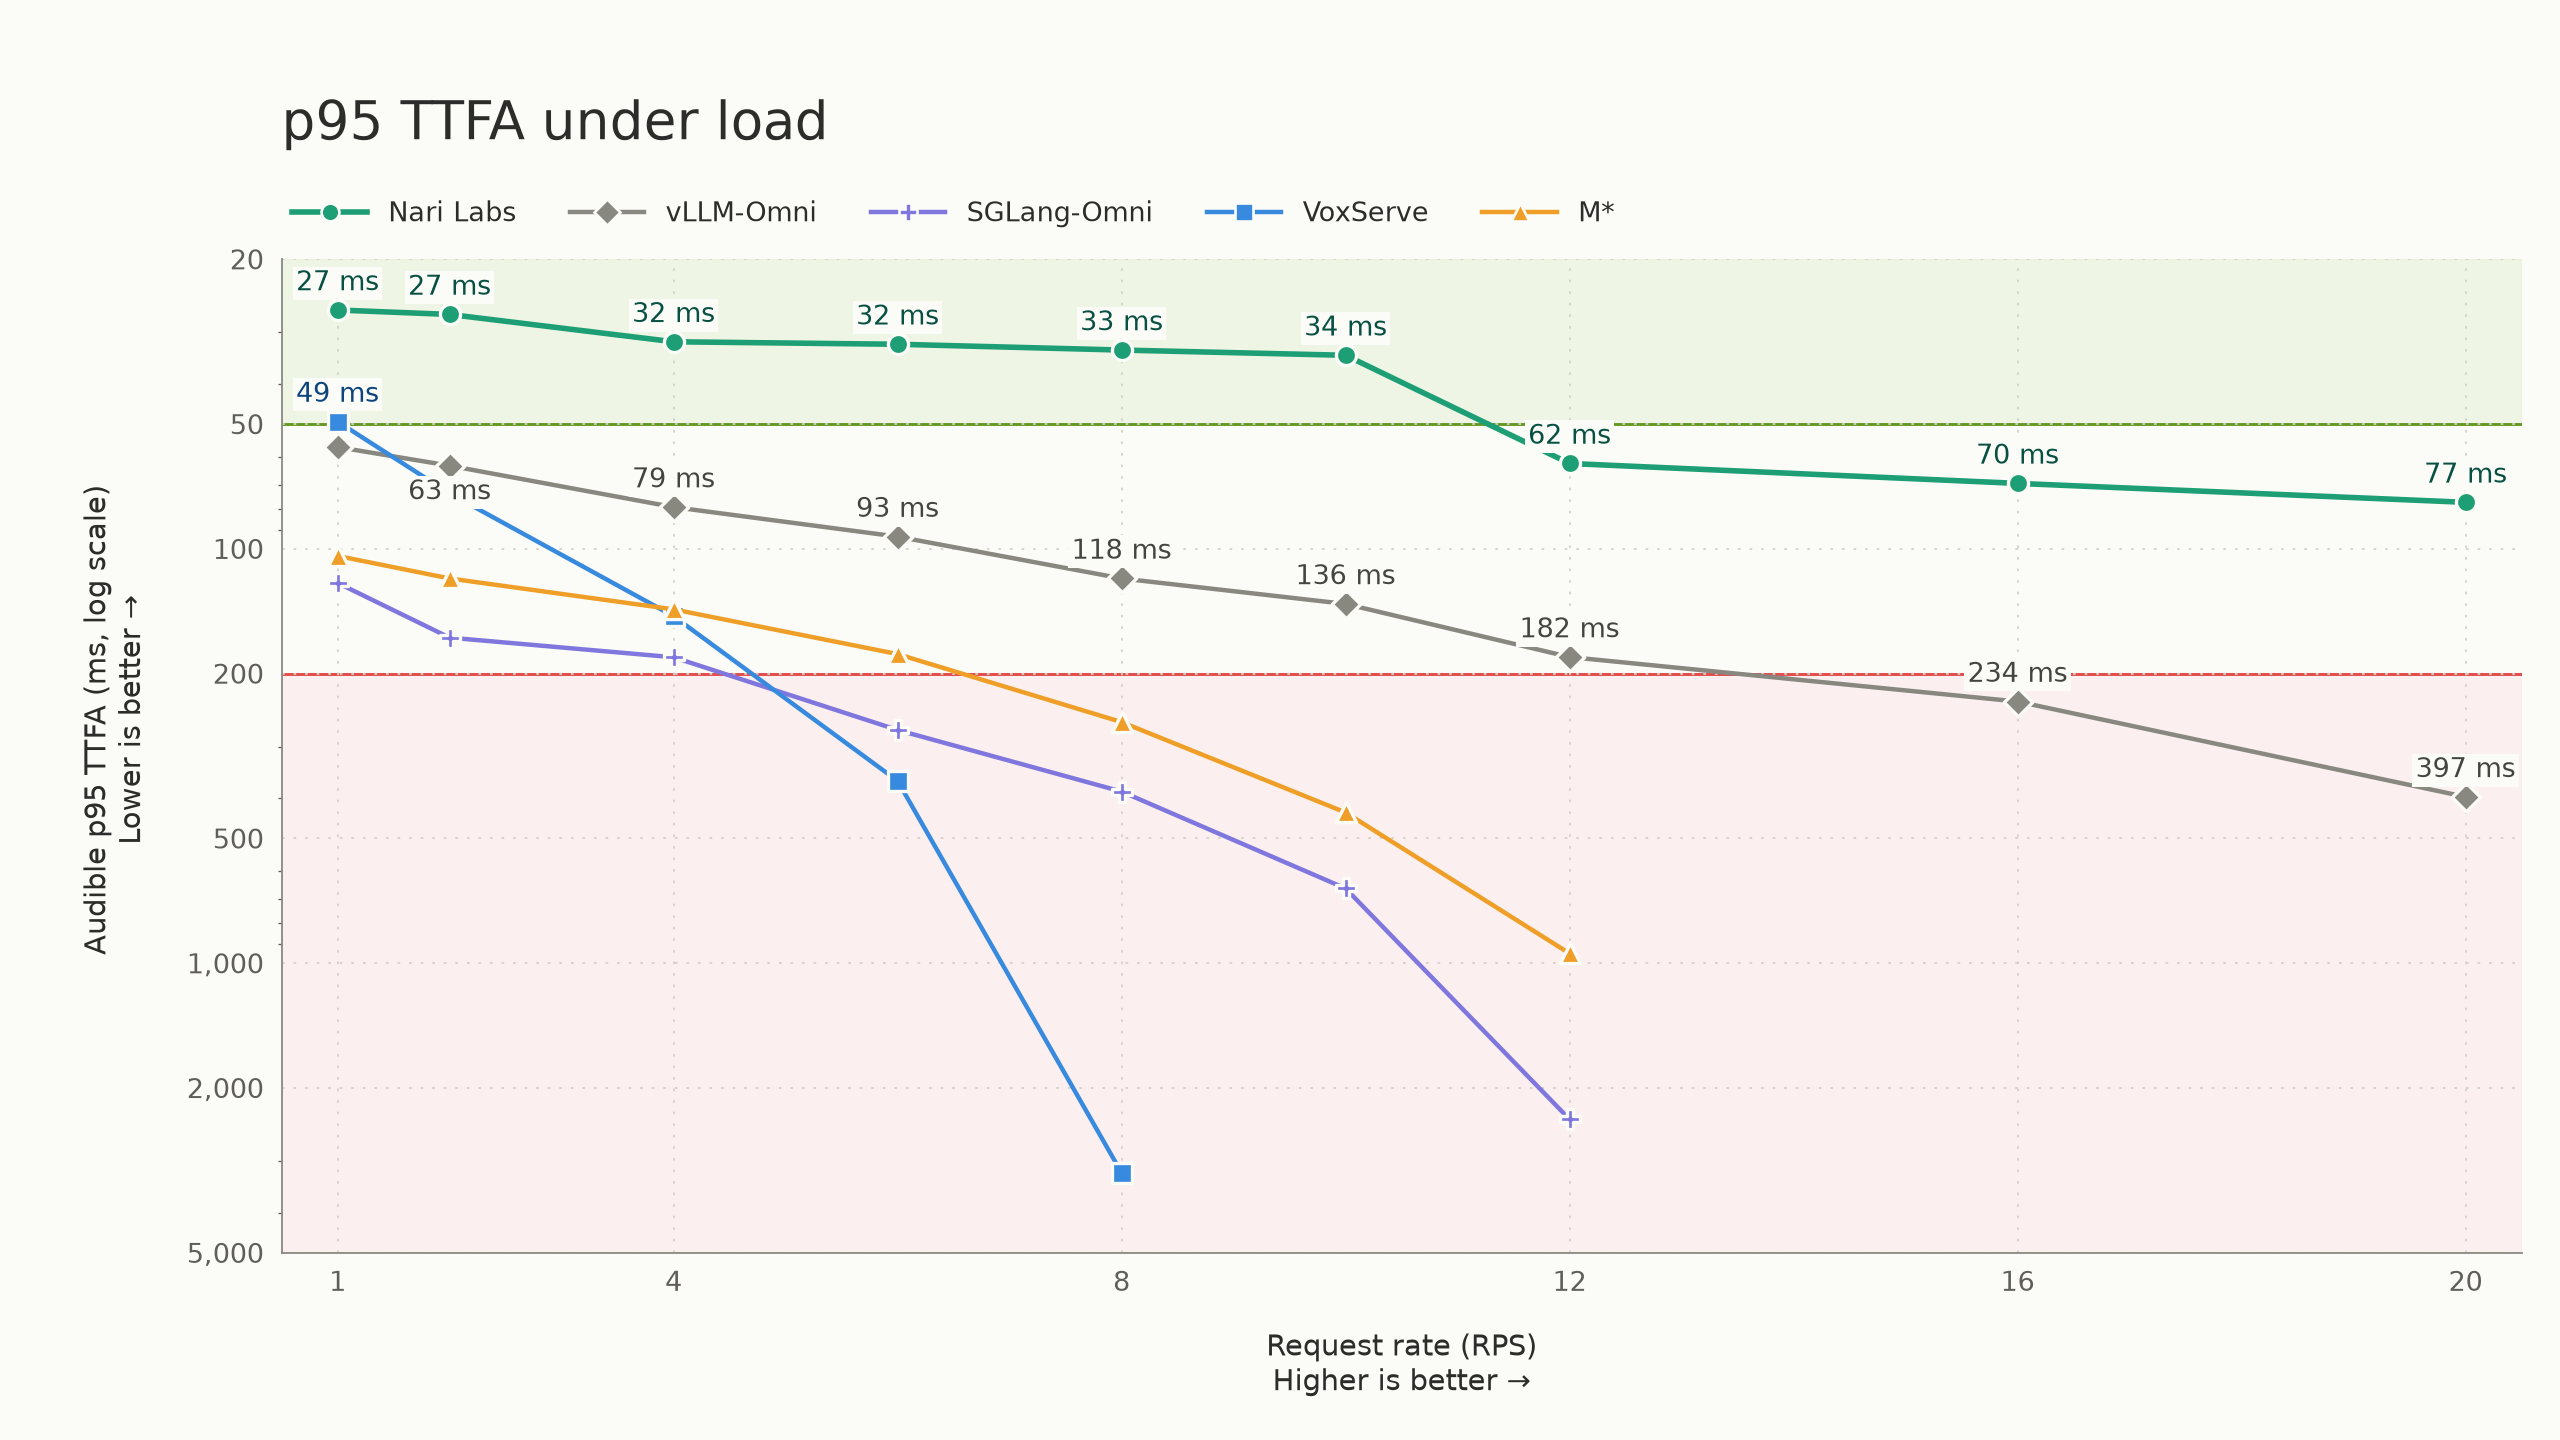
10 RPS with p95 TTFA under 50 ms on a single H100: how we optimized Qwen3-TTS serving.
Summary
Learn how the team achieved impressive response times for their text-to-speech model, Qwen3-TTS, running on a single H100 GPU. The article details their optimization strategies that enable 10 requests per second with a 95th percentile time-to-first-audio under 50 milliseconds.
Comments (44 of ) ⌛