
Compute-Optimal Is Not Cluster-Optimal
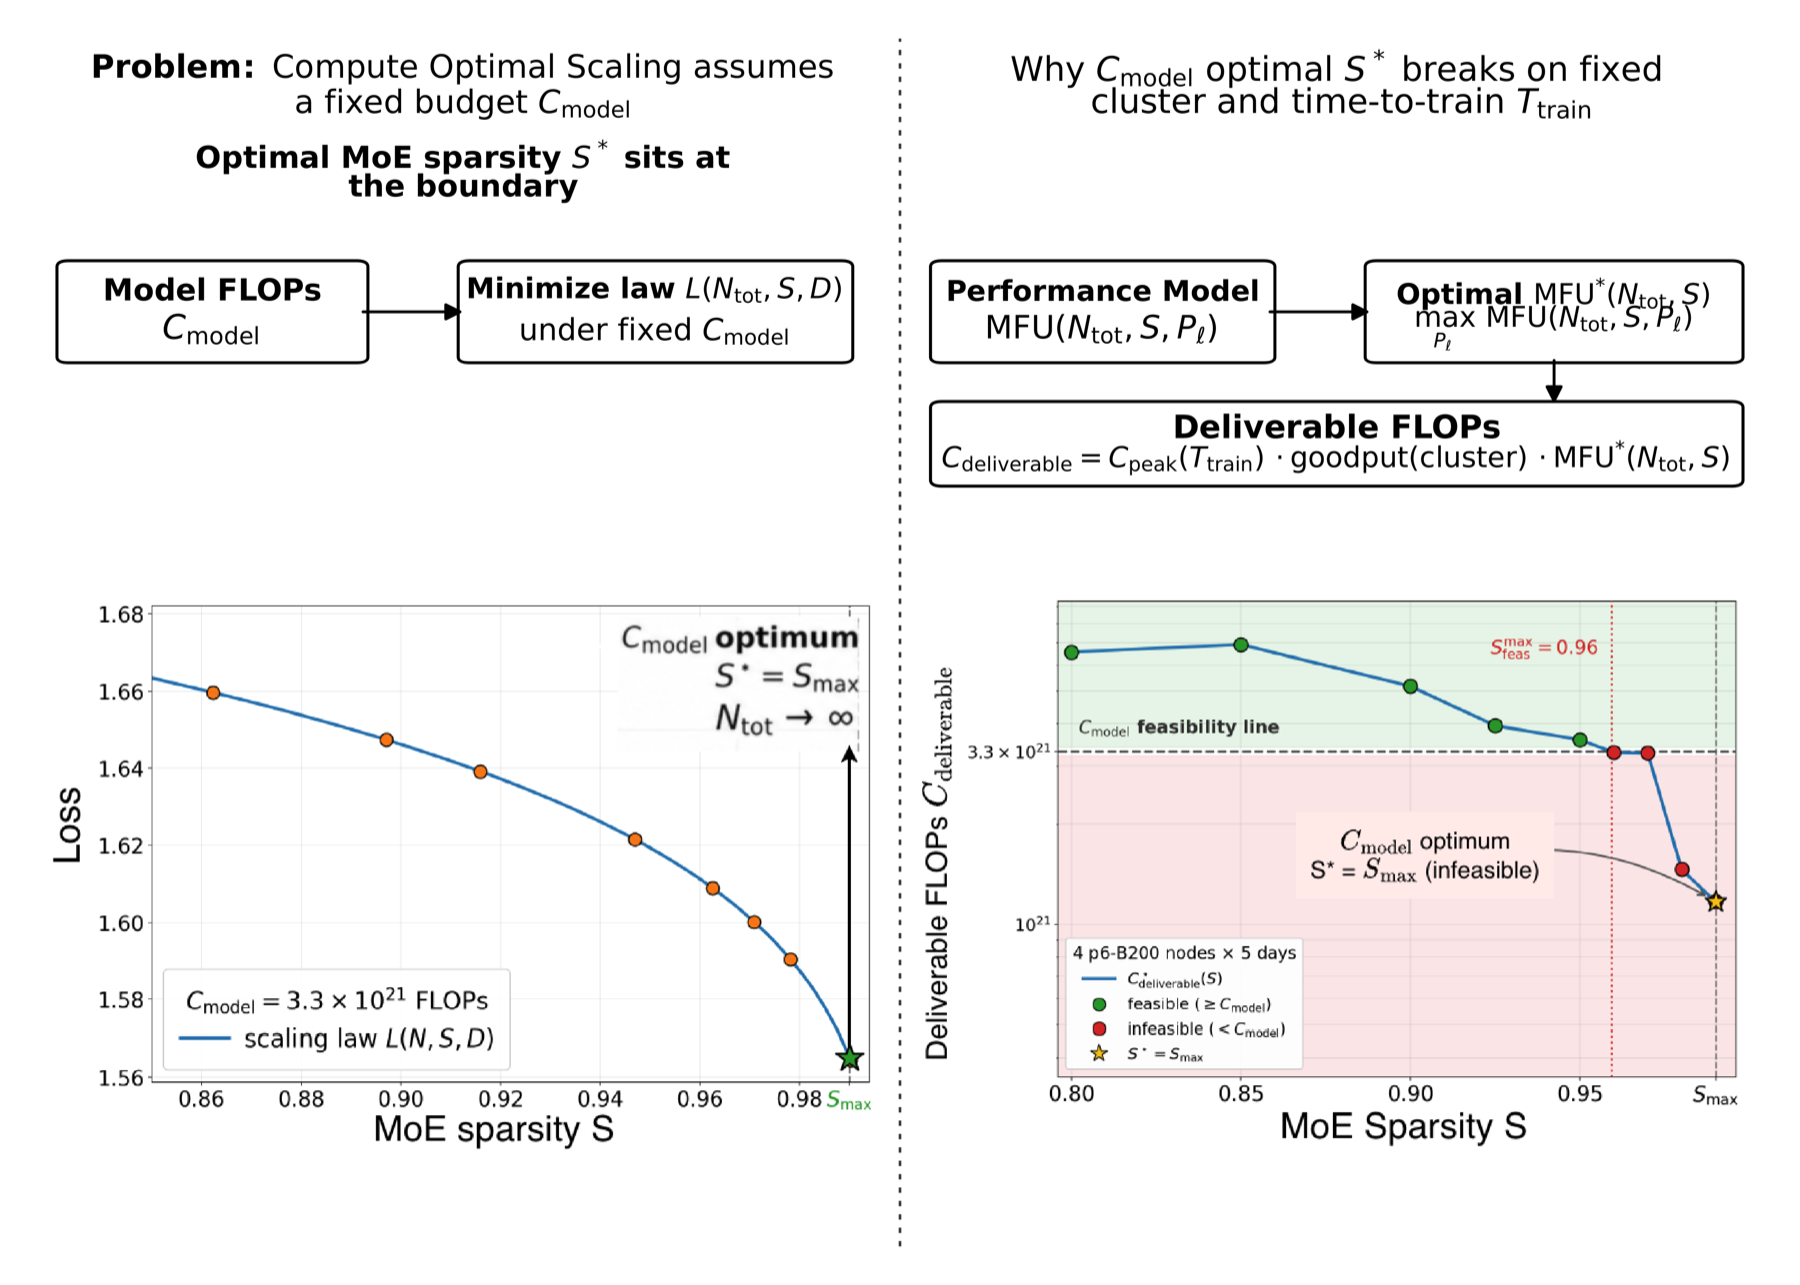
Our new paper folds the systems stage into the scaling-law stage. Price every candidate architecture on what the cluster actually delivers, and the answer changes: the sparsity an MoE
Summary
A recent paper challenges traditional views on model architecture efficiency by linking performance to the specific characteristics of the training cluster. It reveals that the optimal sparsity of a model varies depending on the cluster it operates within, suggesting a need for a more tailored approach to architecture selection.
Comments (0 of ) ⌛