
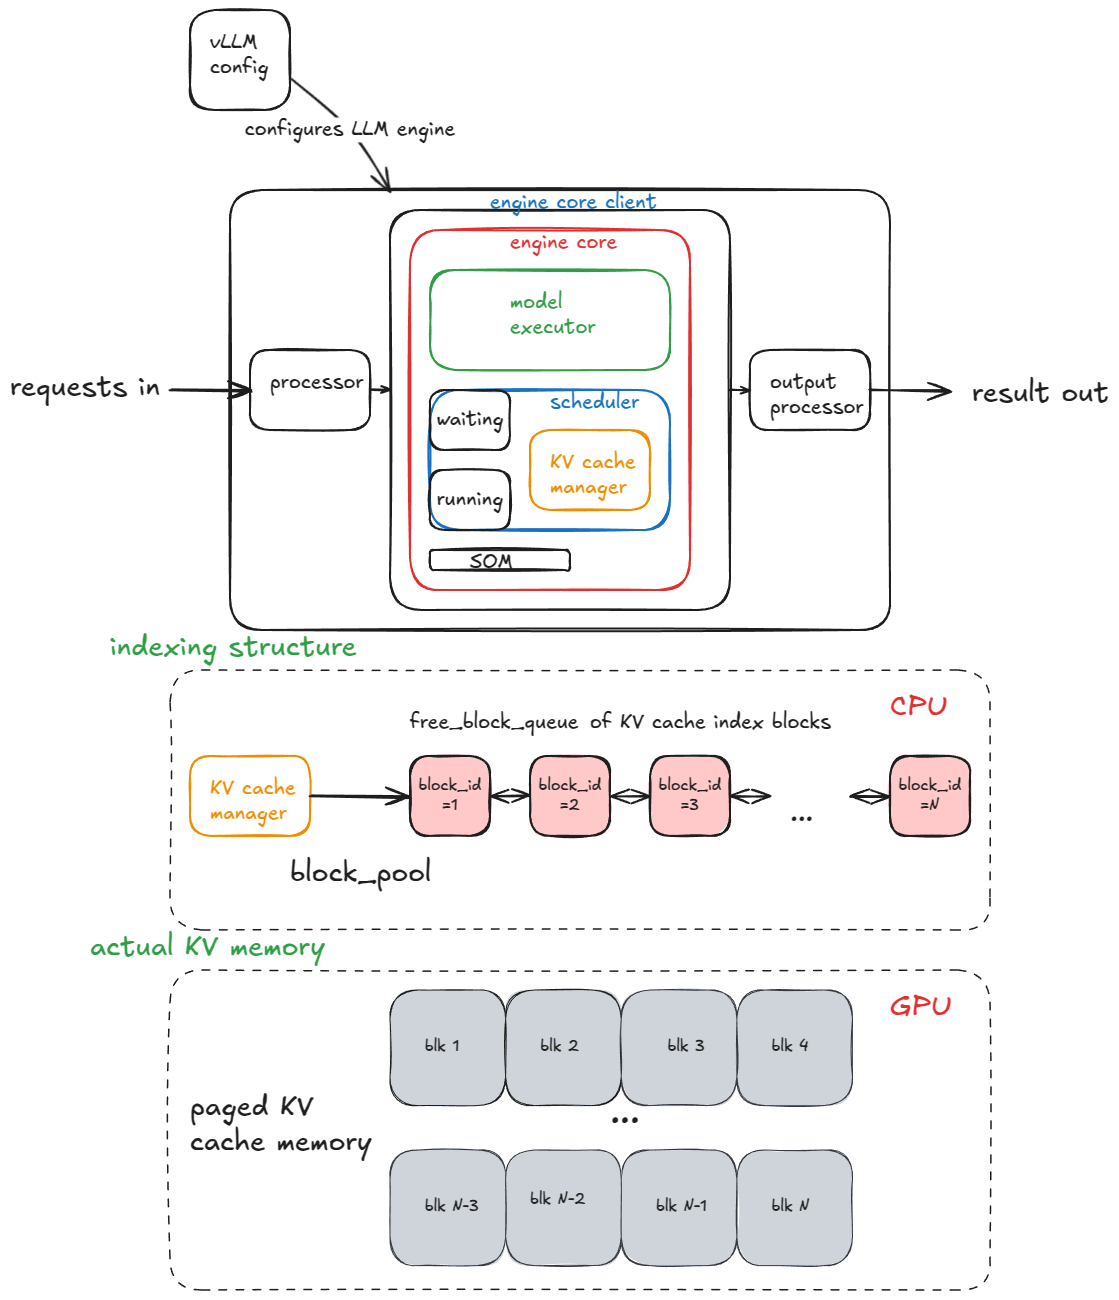
vLLM: Anatomy of a High-Throughput LLM Inference System
From paged attention, continuous batching, prefix caching, specdec, etc. to multi-GPU, multi-node dynamic serving at scale.
Summary
The article details the technical components of a high-throughput inference system for large language models, including advanced techniques like paged attention and prefix caching. It also covers the challenges and solutions for scaling across multiple GPUs and nodes.
Comments (8 of ) ⌛