
Popping the GPU Bubble
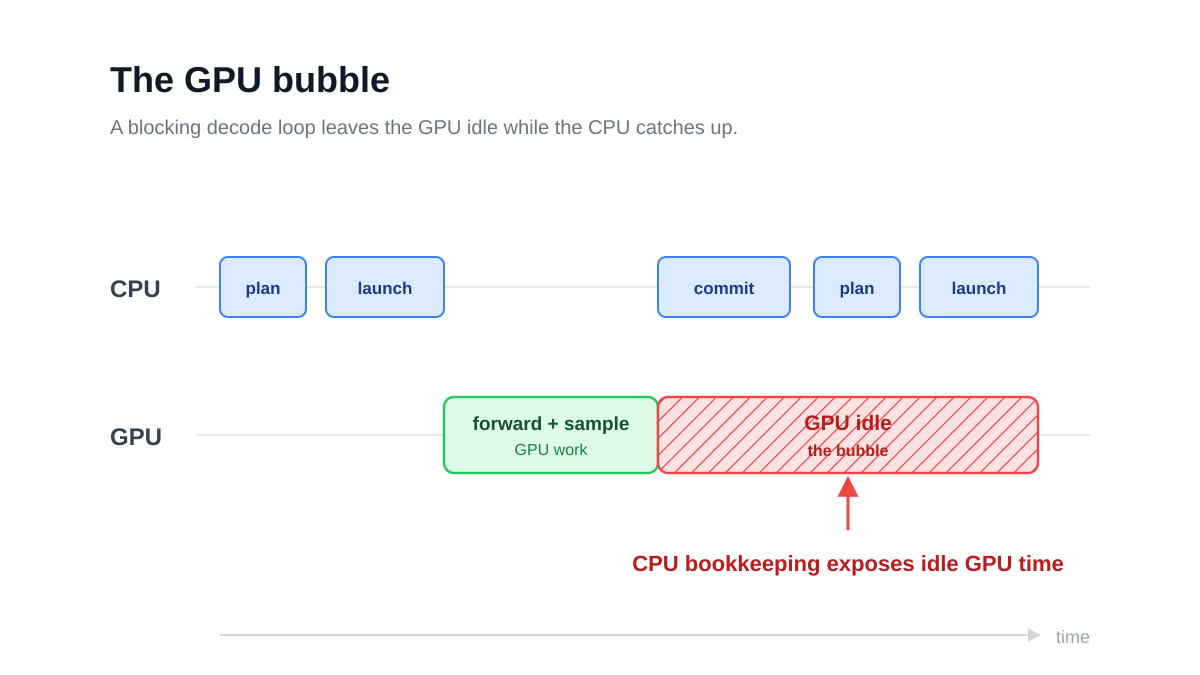
Photon, Moondream's inference engine, achieves near-realtime VLM inference (~33ms on NVIDIA B200). This is a peek into how it delivers up to 35% higher decode throughput by optimizing how the GPU works.
Summary not yet generated for this article.
Comments (36 of ) ⌛