
Show HN: Bonsai 1.7B ternary model at 442T/s on M4 Max
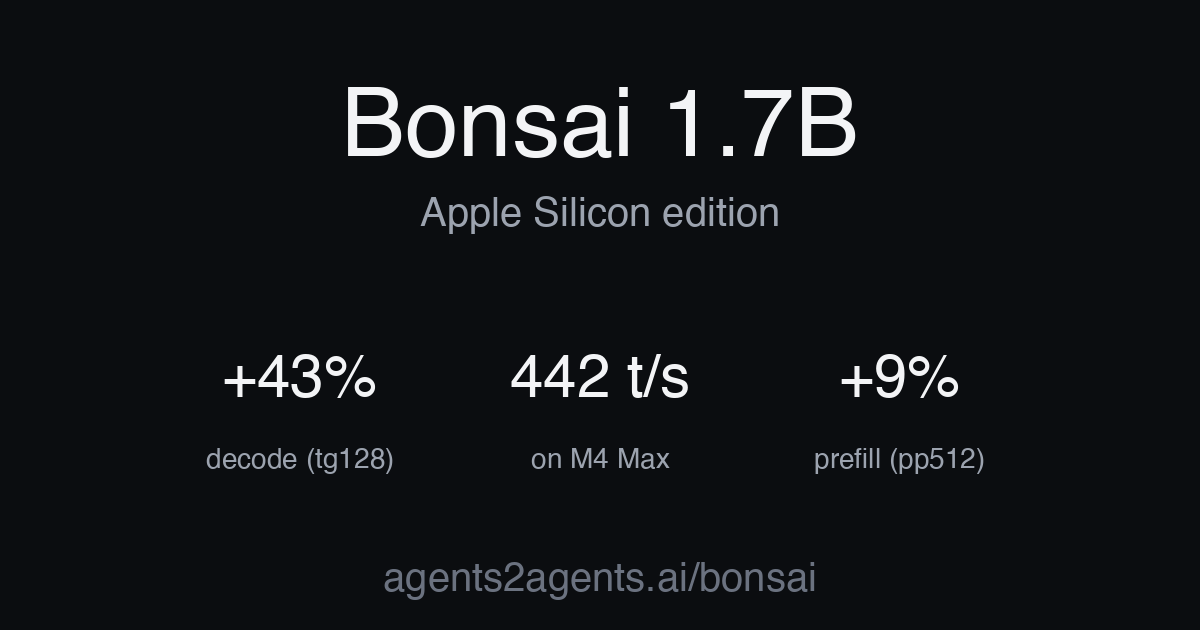
~42% faster decode, ~9% faster prefill vs. the upstream Q2_0 build. All Metal kernels written and tuned by ata, our autonomous engineering agent.
Summary not yet generated for this article.
Original Text
We took a recently released Bonsai 1.7B ternary model from PrismML (https://github.com/PrismML-Eng/Bonsai-demo) and ran our agentic evolution search on it for 6 hours to optimize the Metal kernels. The search was fully autonomous.
Measured against unmodified upstream llama.cpp at the same Bonsai/Q2_0 commit, same M4 Max:
- tg128: 309.82 → 442.42 t/s (+42.0%)
- pp512: 4250.32 → 4622.63 t/s (+8.8%)
Comments (3 of ) ⌛